Nutanix Technology Champion - Nutanix Solution Architect

Julien DUMUR
Infrastructure in a Nutshell

NKP (Nutanix Kubernetes Platform) was on my 2025 roadmap, I pushed it back to 2026 for lack of time, and this chaotic year has just sent it off to 2027. So I have not touched NKP 2.19: what I am telling you here comes from the sessions by Yannick Struyf and Divyansh, which I attended on October 26 in San Jose during Nutanix Tech Connect 2026, where few people in the room had tested this version released the week before.

In this article, I share what I took away about NKP Metal and CN-AOS, the two announcements that take NKP off the hypervisor, and I compare them with the documentation available today. If an acronym loses you along the way, I invite you to read my Nutanix glossary.

NKP Metal, Kubernetes on physical servers
Yannick Struyf, Principal Product Manager for NKP, presenting NKP Metal and what is new in NKP 2.19

Announced at .NEXT last April, NKP Metal ships with NKP 2.19 and deploys Kubernetes directly on physical servers, in the Pro and Ultimate editions. Yannick, Principal Product Manager for NKP, sees three uses for it: GPU-dense machines that customers want to run without an intermediate layer, the edge, where applications are now mostly containerized, and servers to reuse after leaving VMware.

Installation goes through a familiar tool. Foundation Central discovers the nodes and lays down a hardened Ubuntu image, downloaded from the Nutanix portal, on validated hardware that is limited to Dell and HPE for now, with the list expected to grow with each release. If you are not familiar with Foundation, I invite you to read my article on the subject.

Foundation is only used for the initial setup. OS updates and scaling then go through NKP, which updates the existing servers, since you rarely have spares, and relies on labels (“GPU node”, “datacenter 1″…) to add machines automatically when an application grows.

An NTC (Nutanix Technology Champion) asked the awkward question: is bare metal really faster, when some reports from the VMware side claim the opposite? Yannick answered that some workloads need direct access to the hardware, and admitted that even when a cluster on VMs reaches the same performance, some customers want their Kubernetes on physical servers, out of “mindset”. Fairly honest for the person presenting the feature.

That leaves storage. If you already have an NCI (Nutanix Cloud Infrastructure) cluster, the CSI (the Kubernetes storage driver) lets the physical nodes consume its storage. Otherwise, you will have to look at CN-AOS…

The mixed AHV and bare metal cluster

According to Yannick, this is the most frequently requested scenario, and I understand why: a highly available Kubernetes cluster needs three control planes, and dedicating three physical servers to nodes that will never use all their resources is expensive. With NKP 2.19, you deploy your cluster on AHV, with control planes and workers as VMs, then you add an NKP Metal node pool with your GPU machines.
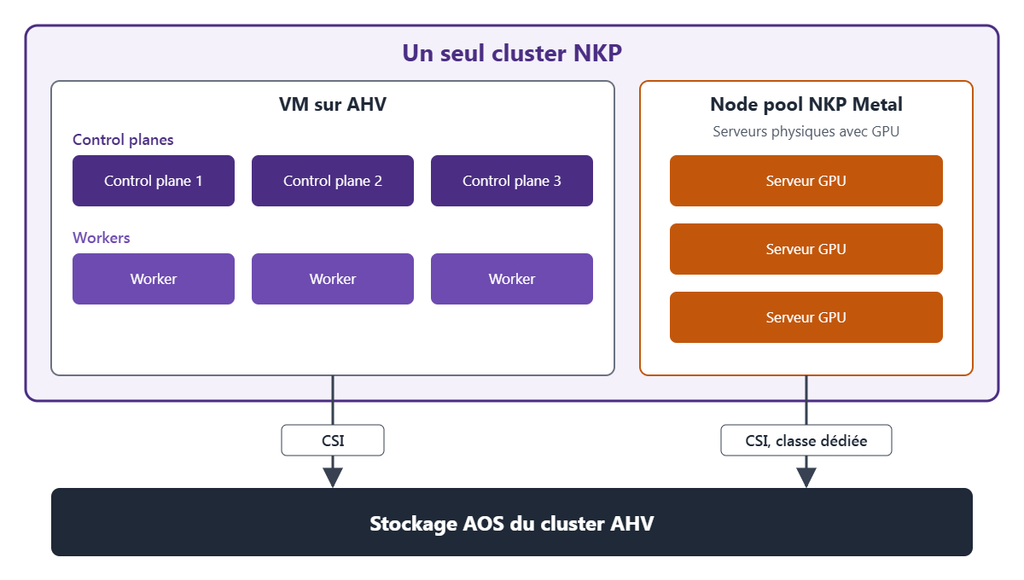
Diagram of a mixed NKP cluster, with virtualized nodes on AHV and a node pool of physical servers equipped with GPUs

Storage was the blocker. In bare metal mode, the CSI lost track of the topology and of the volumes attached by the hypervisor. It now knows which nodes can use them, with a separate storage class for bare metal.

One NTC admitted that this gap had made their team give up on NKP two years earlier. “Huge improvement” was their verdict, and another summed up the room in one word: “Sold.”

What NKP 2.19 changes day to day

NKP Metal takes center stage, yet these changes will affect far more people.

  • The unified registry: in connected environments, container images used to come from several repositories. They are converging on a single Nutanix registry, based on Docker Hub, with a token created on the Nutanix portal to deploy the management cluster. Dark sites and mirror registries are not affected. Since this effort spans the whole company, one NTC, tired of negotiating URL lists with security teams, slipped in a heartfelt “you just made my day”.
  • Projects 2.0: with Prism Central 7.6, a cluster’s VMs, persistent volumes and OS images are attached to the same project, whereas you previously had to grant access to each resource separately. This makes RBAC (role-based access control) much simpler, especially for service providers.
  • The AHV VM Operator: it describes a VM, Windows included, as a Kubernetes resource, and can expose it through a LoadBalancer or ClusterIP service. Unlike OpenShift Virtualization, the VM does not run inside the Kubernetes cluster: it is deployed on AHV.

Upgrades, so far done from the CLI, can now be run from the UI or declaratively with GitOps, with checks before and after the operation. The order is still dictated by the NKP 2.19 documentation (“Upgrade Nutanix Kubernetes Platform”): the management cluster first, with Kommander then the NKP CLI, and the workload clusters next, one at a time, starting with their platform applications. On a cluster managed with GitOps, control planes are replaced before workers.

CN-AOS, AOS storage without a hypervisor

Divyansh, who leads storage product management at Nutanix, starts from the question NKP Metal raises: without a hypervisor, where does the storage come from?

The answer is CN-AOS (Cloud Native AOS). The AOS storage engine runs in Kubernetes pods, the cloud native equivalent of CVMs (the controller VMs of a Nutanix cluster), and relies on the nodes’ local disks. You get thin provisioning, data locality, RF2 (two copies of each piece of data) and inline compression, with deduplication and erasure coding announced for later. The CSI exposes two access modes, RWO (write access from a single node) and RWX (from several nodes), which lets you serve a file share or home directories without buying yet another storage solution.

CN-AOS first launched on AWS, on EC2 instances orchestrated by EKS. Divyansh says it is available with NKP 2.19, promises an improved experience with NKP 2.21 and does not rule out opening it up to OpenShift on bare metal.

The documentation is more cautious: the CN-AOS 1.0.0 guide dated June 17, 2026, which predates NKP 2.19, only covers EKS. It still gives a rough idea, to be checked on NKP Metal: 3 to 15 nodes, and up to 48 GiB of memory and 16 vCPUs reserved per node. On a server bought for its resources, you will have to size for that.

NDK to protect applications
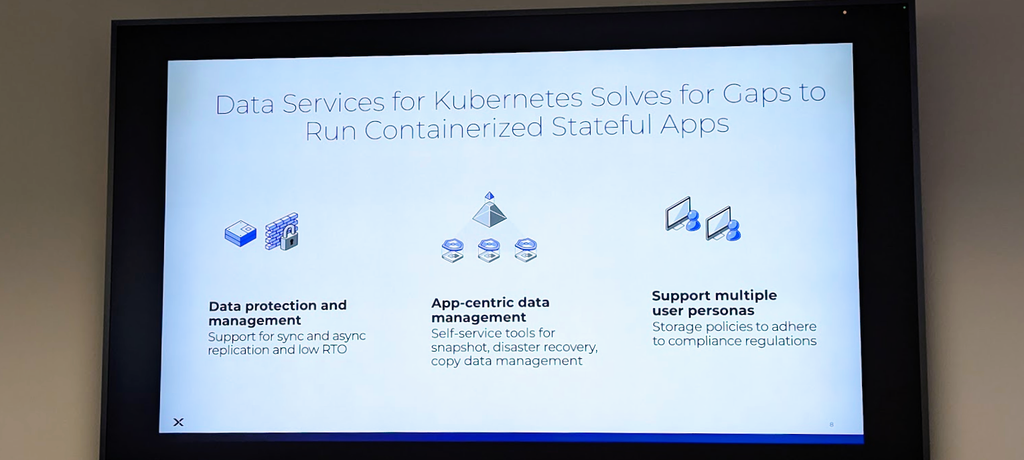
Slide presenting NDK data services for running containerized stateful applications

Divyansh sees NDK (Nutanix Data Services for Kubernetes) as the piece that lets you move beyond stateless applications, with snapshots and synchronous or asynchronous replication that application teams drive themselves. The goal is to cover NKP on AHV and NKP Metal with CN-AOS, then eventually the management cluster, whose backup currently goes to S3 with Velero, without application data.

The NDK 2.3 release notes, dated September 21 and therefore older than NKP 2.19, suggest waiting for the next compatibility matrix before getting carried away. They bring a web interface, included in the Helm chart, and require at least NKP 2.18.0, AOS 7.5.1 and Prism Central 7.5.1, but neither NKP Metal nor CN-AOS is listed.

Three limitations are worth keeping in mind:

  • Consistency: it is not guaranteed between file shares and block volumes of the same application (ENG-823426).
  • Replication: it goes from one cluster to a single other cluster (ENG-756494), with the same Kubernetes distribution on both sides.
  • CN-RWX: it only appears in a known issue (ENG-923368), with pods stuck in Terminating after a site-wide storage failure.

On the CN-AOS side, the guide limits DR (disaster recovery) on EKS to asynchronous replication, with an RPO (the maximum acceptable data loss) of one hour or more. That is a long way from the synchronous replication announced for NDK in general.

My take on NKP Metal and CN-AOS

I have not tested anything, so I will stick to the use cases that seem most obvious to me: dense GPU-based AI infrastructure, disconnected or branch office edge environments, and IT departments looking to unify their management. On these three fronts, removing the hypervisor makes sense, and the mixed cluster strikes me as the most reasonable way in.

Above all, these sessions made me want to really find the time to get into it, before NKP slips onto my 2028 roadmap.

Yannick also presented what comes next, but it is under NDA, so you will not get any more out of me… If you want other perspectives on that day, I invite you to read the write-ups by Jeroen Tielen and Patrick Damen.

And you, are you considering running Kubernetes without a hypervisor?
Read More

Monday, October 26, 8 a.m., in front of the 1740 Technology Drive sign in San Jose: this is where Nutanix Tech Connect 2026 kicks off, at Nutanix headquarters, and I show up wearing the “Unstoppable” hoodie that had been with me for the whole trip, a name that took on its full meaning over the weekend. If you missed the previous episode, I tell the story of the 53 hours it took me to reach California in this article.

A small consolation after breakfast: Drew Plaster hands me the order I had placed on the Nutanix Store and had shipped to his place to avoid excessive shipping costs. Inside, an NKP t-shirt that could not have been better timed given the day’s agenda, a blanket because winter is coming, a leash for the dog, and a personal gift slipped in by Drew, a Nutanix-branded lightsaber…

White and chrome lightsaber with the Nutanix logo lying on an NKP t-shirt and an orange hoodie

There are 25 of us NTCs, from 6 countries, and I am the only French member of the NTC program. It is my second time here after the 2024 edition, and this first day revolves almost entirely around NKP (Nutanix Kubernetes Platform), which takes up four of the seven sessions.

Part of what we were shown is under NDA: I am sharing everything I am allowed to share here, and the roadmap slides will stay on my phone.

Welcome to Nutanix Tech Connect 2026!

Before going in, the mandatory photo session in front of the sign, then inside in front of the big glowing X in the lobby, everyone taking turns to pose.

The French Nutanix Technology Champion posing in front of the big glowing X in the lobby of Nutanix headquarters

At 8:20, just enough time to grab a coffee and a small cake, Angelo Luciani welcomes us to Nutanix Tech Connect 2026. First tip of the day: learn Kubernetes, with the KCNA (Kubernetes and Cloud Native Associate), the CNCF’s entry-level certification, as the target. Noted, but for me it is a long-term goal: before aiming for an exam, I first need to dig seriously into NKP and Kubernetes, and the rest of the day was going to help with that.

Angelo then presents the proof of concept of a portal dedicated to the NTC program that he is working on, and asks for our feedback to improve this first draft. I found it excellent, and we did not hold back on our comments right there in the room.

Selfie of Julien Dumur with Jeroen Tielen et Kim Mount, other NTCs, in the Tech Connect 2026 meeting room

The future of the program came back on the table at 12:30, with a workshop called “The next decade of NTC starts here”, where we worked in groups on what the program should look like in 2036. I cannot tell you more, what we discussed stays between NTCs for now.

Thomas Cornely, a Frenchman in Silicon Valley

At 9:00, Thomas Cornely, EVP Product Management, joins us for his welcome talk, and I find out that I am not quite the only French person in the room: he is originally from France and has lived in Silicon Valley for 25 or 26 years. He walks us through his career with a frankness I liked: early days at France Telecom R&D, then Silicon Valley, where he worked at Symantec on the Veritas Storage Foundation line, then Greenplum, Violin Memory, five years as Chief Product Officer at Nexenta and a few months at Rubrik, before joining Nutanix in the spring of 2020, right at the start of COVID, with the job of bringing coherence back into a portfolio that had become very fragmented. He describes himself as “the janitor”, the one you call in to clean things up. I find his career very inspiring and frankly impressive.

Thomas Cornely, EVP Product Management at Nutanix, speaking to the NTCs at Tech Connect 2026

His team is about 150 people, including some fifty highly technical solutions engineers who work with the largest customers and produce the NVDs (Nutanix Validated Designs). Every NVD goes through real field testing, during which the team “breaks a lot of things” before engineering fills the gaps. That is why some NVDs come out in nine months and others take two years.

On the portfolio, he stresses how the building blocks fit together. Flow is now treated on the same level as AHV, under the same engineering team. NDB (Nutanix Database Service) has its place in a world where agents will have to work on database clones rather than on production. As for NKP, it is a success story after several internal attempts that had fizzled out. The D2iQ acquisition, which he drove himself and calls “almost a stroke of luck”, brought the team and the open source culture that were missing, with a clear stance: a Kubernetes designed for operators, where OpenShift targets developers first.

More surprising, he tells us that last December, just before flying back to France for the holidays, he decided to “blow up” the entire 2026 roadmap to invest heavily in AI infrastructure. And VMs are not going away: an autonomous agent that runs for days needs access to data with the right permissions and has to stay available, exactly like a virtual desktop, a field Nutanix knows inside out.

Time for questions. John Heim asks whether the external storage support announced at .NEXT 2025 with Dell and Pure Storage had been planned for a long time or forced by the market. The answer from the man who drove that decision: opportunity. By raising prices massively after buying VMware, Broadcom created customers who still like the technology but no longer like the vendor. And for Thomas, hyperconvergence has always been a way to get to simplicity: if Nutanix can deliver the same thing with a Pure Storage array or compute-only nodes packed with GPUs, all the better.

René van den Bedem then asks him about the next ten years, beyond AI. In an industry where everything changes every six months, ten years is an eternity, and what comes next will involve AI built into the products as much as the AI Nutanix uses internally for its own teams: a huge playground, in short…

One last anecdote: Thomas cannot stand ten-page documents that repeat the same thing fifty times, and he enforces a two-page maximum. So I will try to stay concise for the rest of this article…

NKP and AI: Kubernetes built for GPUs

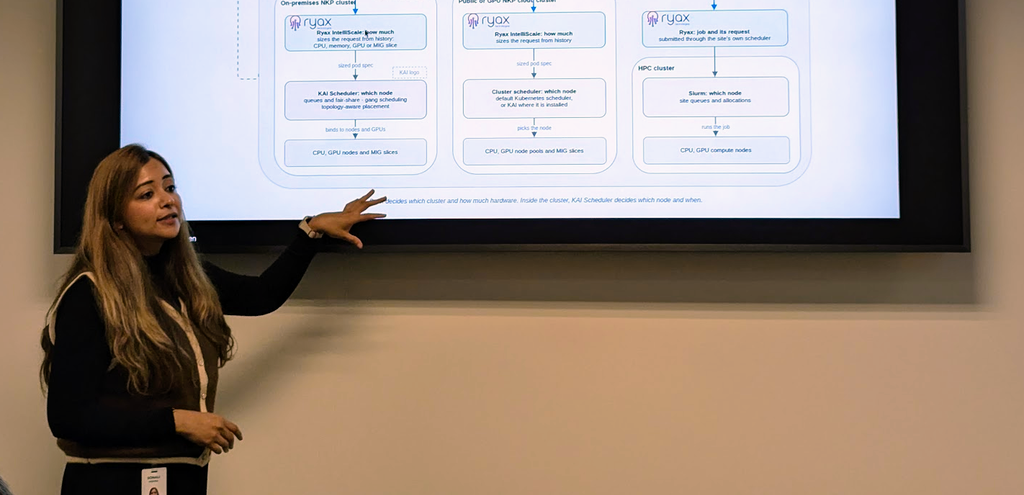
At 9:40, Sonali Mishra, NKP Principal Product Manager, takes over. She comes from D2iQ, where she launched the very first version of the product, back then DKP 2.0, and she opens with a slide that made quite an impression in the room: on Nutanix infrastructure, NKP has overtaken OpenShift and Rancher, both in number of customers and in number of deployed cores.

Sonali Mishra, NKP Principal Product Manager, presenting NKP to the NTCs

Her topic of the day is AI, and her starting point is simple: nearly 99% of AI workloads are containerized, so they will end up on Kubernetes, and more and more often directly on physical servers fitted with GPUs. To get NKP ready for these workloads, Nutanix opened three work streams. The first one is the CNCF AI Conformance certification, obtained about six weeks earlier, which guarantees that an AI application running on vanilla Kubernetes will also run on NKP. The standard moves so fast that three new mandatory requirements have already been added since.

The second one is the AI Catalog, which deploys in one click all the tooling an MLOps team needs: the NVIDIA and AMD GPU operators, the KAI Scheduler, Slurm through the Slinky operator, Kueue, KServe and Envoy Gateway for inference, Nutanix Enterprise AI, Jupyter, Kubeflow, Milvus and the NKP MCP server. The KAI Scheduler caught my attention: where the Kubernetes scheduler spreads workloads across three GPU nodes, it packs them onto a single node and keeps the other two free. The third one is support for AMD GPUs on par with NVIDIA, to give customers a choice in the middle of a hardware shortage. Intel, on the other hand, is not on the agenda for lack of demand.

Sonali also shows us AI Navigator, the assistant built into NKP, trained on eight to nine years of support cases and KB articles. It answers questions about the state of your clusters but does not take any action yet (customers did not want that so far), and it accepts your own model for air-gapped environments.

Last announcement, and not the least for a French reader: Nutanix has acquired Ryax Technologies, a French company. Its IntelliScale product observes workloads over time to correct the resources developers systematically overestimate. Combined with the KAI Scheduler’s bin packing, the first benchmarks point to 30 to 40% optimization.

NKP 2.19 and CN-AOS: see you in a dedicated article

At 10:50, Yannick Struyf, NKP Principal Product Manager, moves on to what’s new in NKP 2.19, released the week before, with NKP Metal in the spotlight, Kubernetes directly on physical servers. Divyansh, who leads storage product management at Nutanix, follows at 11:40 to present CN-AOS (Cloud Native AOS), the AOS storage engine packaged as Kubernetes pods. These two sessions are too rich to fit in a few lines: I am giving them a dedicated article, coming very soon…

Yannick Struyf, NKP Principal Product Manager, presenting what's new in NKP 2.19

NKP Insights: one card instead of nine hundred alerts

After lunch and the workshop, Sonali is back at 13:15 to talk about NKP Insights, the security and observability component included in the NKP Ultimate edition. The numbers she puts on screen set the scene: 82% of container users run Kubernetes in production, up from 66% in 2023, 89% of organizations had at least one container or Kubernetes security incident in the last twelve months, and 46% lost revenue or customers because of it.

Title slide of the NKP Insights session on Kubernetes security at fleet scale

The problem grows with the size of the fleet: configuration drift, deprecated APIs blocking upgrades, certificates expiring without warning. She gives the example of a customer running NKP on 60 to 70 ships who has to upgrade them every six months. NKP Insights relies on open source building blocks at every stage: Harbor and Trivy at build time, with the hardened images coming from the RapidFort partnership, Gatekeeper at deployment, Trivy and Polaris for continuous scanning, and Falco for runtime security, with general availability planned for December.

The added value is the engine that correlates all these signals on a graph and only raises one card per problem, with the cause and the fix to apply. Each card can then be muted, snoozed or resolved. Everything runs inside the cluster, air-gapped included, with the vulnerability databases shipped in the releases, and each insight is a Custom Resource governed by NKP RBAC.

The demo got a reaction from several NTCs, who would like to see the rest of the Nutanix products handle alerts the same way. One of them summed it up with an example every Nutanix admin will recognize: one NGT certificate expires, and nine hundred alerts come pouring in…

NKP topologies: quorum, quorum, quorum!

At 14:15, Yannick comes back for a session on NKP deployment topologies and resilience, with an approach I really liked: start from the failures rather than from the features.

 Title slide of the session on NKP deployment topologies and resilience

First case, losing the management cluster: no impact on running workloads, but no more scaling or upgrades until it comes back. NKP backs it up with Velero to S3-compatible object storage, Nutanix Objects for instance, and restoring it means creating a fresh management cluster and importing the backup into it, a bit like PCBR for Prism Central. Be careful, only the metadata is backed up, not the applications.

Then come the Kubernetes nodes, and the word “quorum”, which is the reason for the three control planes, came up so often in the room’s answers that it became the running joke of the afternoon. The classic trap is elsewhere: without a placement rule, AHV can put two control planes on the same host, and losing that host breaks quorum, and with it every write to the Kubernetes API. And a single anti-affinity rule for all the VMs in the cluster is not enough, you need one for the control planes and one for the workers, with enough hosts behind them.

Across three datacenters, NKP can spread control planes across failure domains, but etcd requires latency below 5 to 10 ms between sites and storage is not replicated: CSI 3.x creates the volume on the AOS cluster of the worker using it, and nothing more. Across two datacenters, the recommendation is clear: one Kubernetes cluster per site, a load balancer in front, and NDK to replicate stateful applications.

Yannick wrapped up with the “perfect solution” someone once pitched to him for Kubernetes across two datacenters: deploy five control planes…

Networking, reception… and suitcase

At 15:15, the sessions give way to discussions between NTCs, then to the reception from 17:00, a chance to carry on the day’s conversations over a beer. A reception during which Angelo, our host, treated us to a top-flight karaoke performance!

Two NTCs raising a beer at the Tech Connect 2026 reception

And when I got back to the hotel, a nice surprise was waiting for me: my suitcase, finally in from Frankfurt with two hastily stuck “RUSH” tags, one for each Lufthansa flight.

Baggage tags marked RUSH on a suitcase handle

Tomorrow, agentic AI will be at the heart of the agenda, and I will finally have a change of clothes…

Read More